Factored
Evaluation & Production Evals
Build and defend an evaluation harness for AI agents: choosing graders, judging with LLMs, testing RAG and agents, and keeping evals running in produc
About This Course
Evaluation and Production Evals is the sixth week of Jed-AI Academy's agent-building track. By this point you have built agents; this course is about proving they work, catching the ways they quietly fail, and keeping that trust in place after the agent ships. It pairs short, verified vendor courses with original material written specifically for this program, so each subsection opens with a well-established outside course and then goes further into territory that course does not cover.
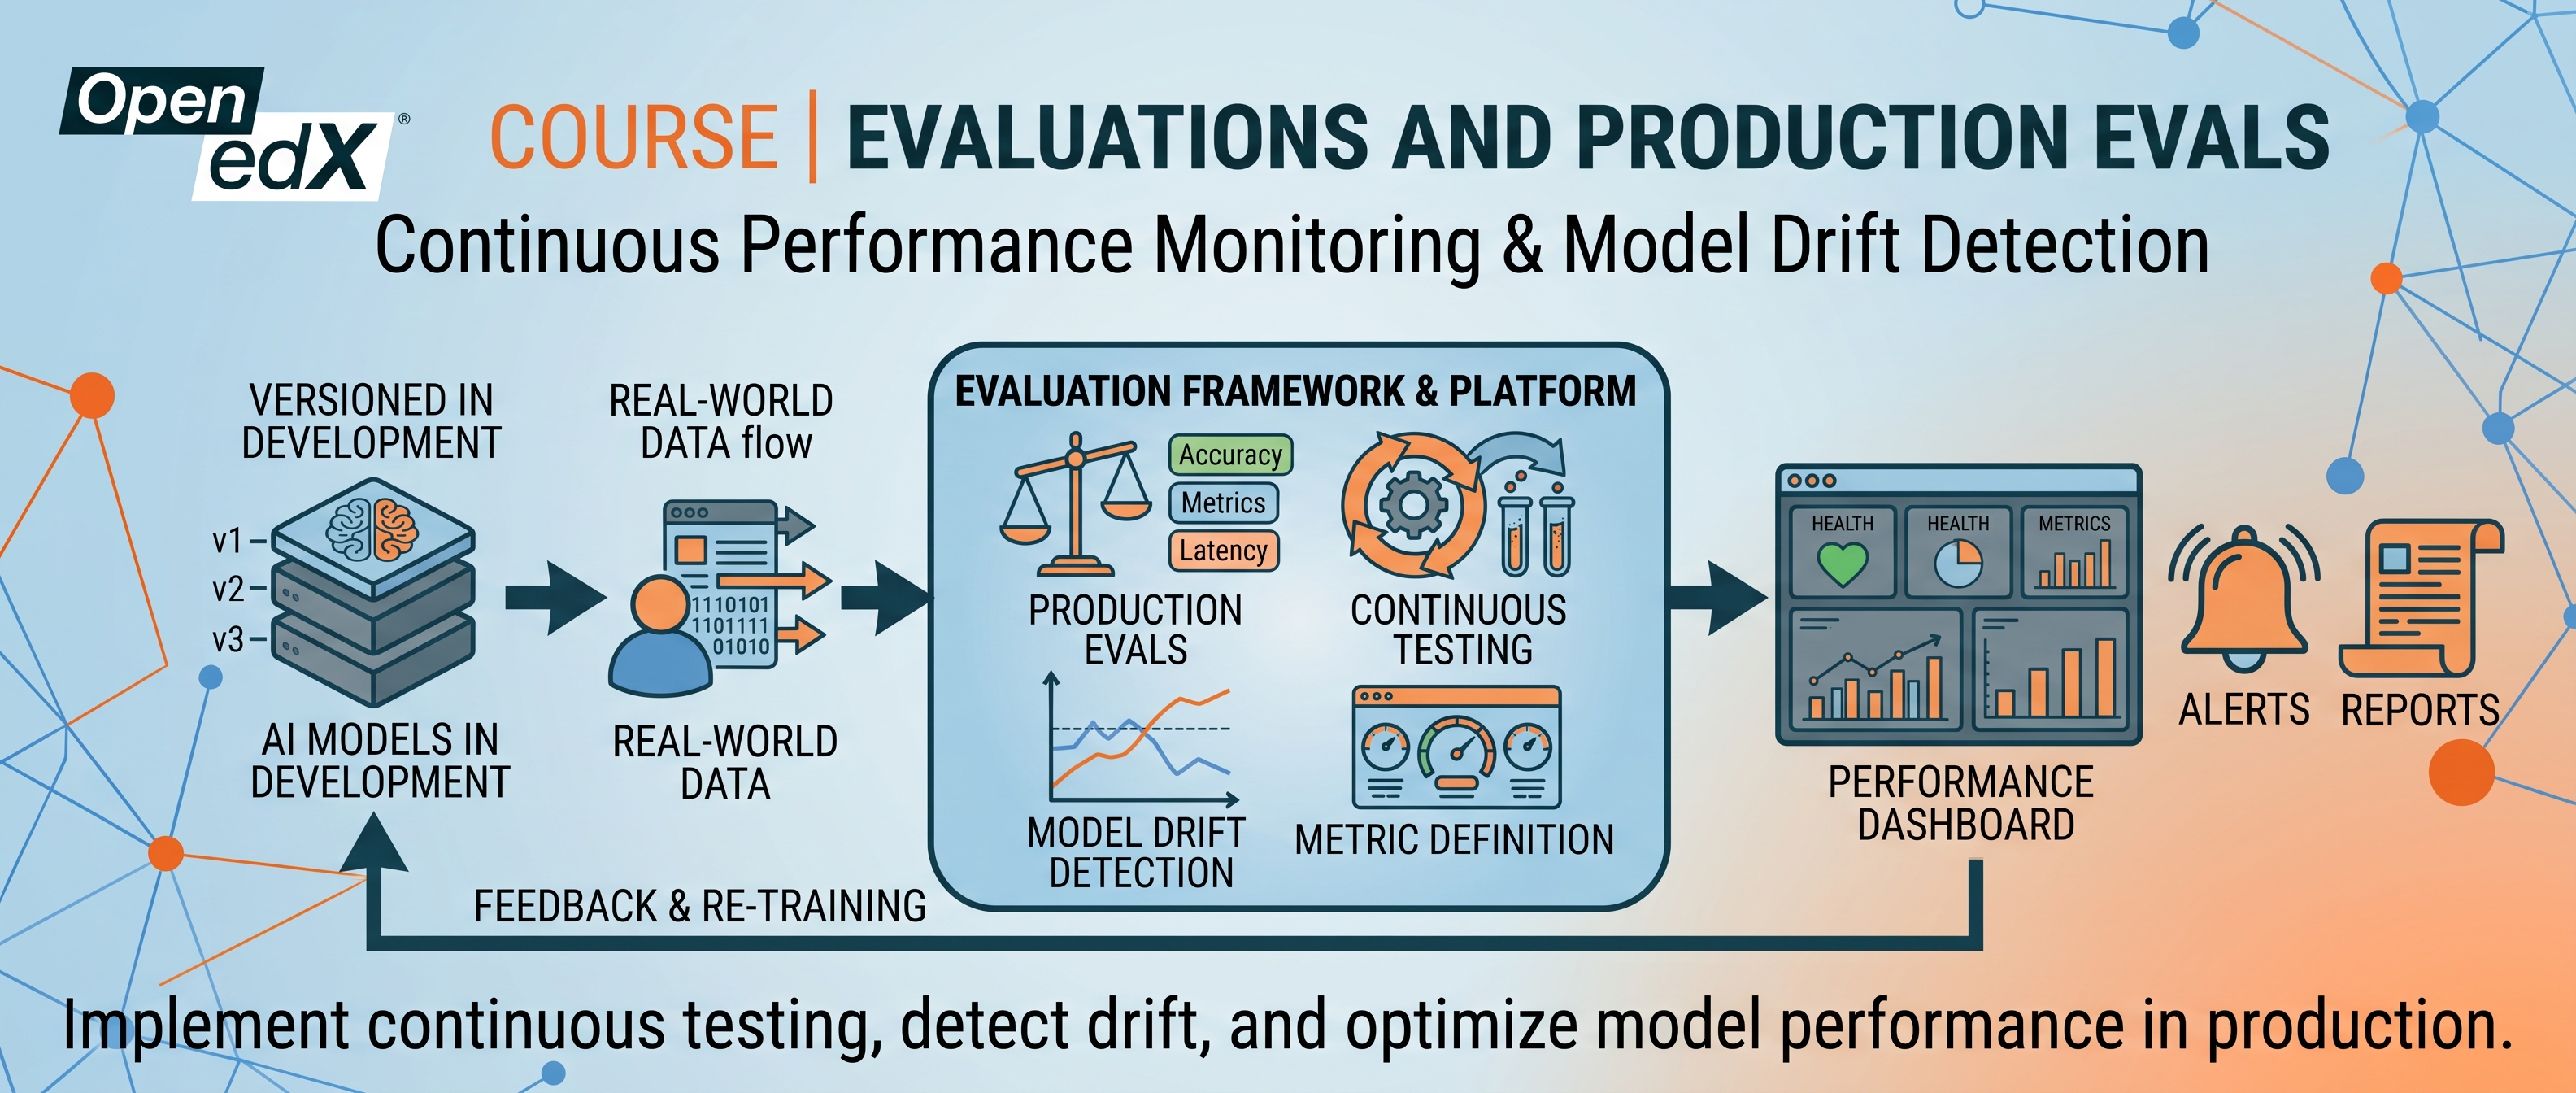
The first half of the course builds the vocabulary and judgment every eval effort depends on: why evaluation exists as its own discipline, how to choose between code-based, model-based, and human graders, and how to build and calibrate an LLM-as-a-judge so its scores can actually be trusted. From there the course moves into evaluating retrieval-augmented generation pipelines and agents specifically, including the non-determinism that makes agent evaluation harder than evaluating a single model call, and how to grade a multi-step trajectory rather than just a final answer.
The second half turns from evaluating a system once to keeping it evaluated over time. You will build a regression suite and a golden dataset from real failures, wire that suite into CI/CD so a change cannot silently break behavior that used to work, and build the capture-score-monitor-alert loop that catches problems evaluation missed before release. The course closes with an honest look at where evals themselves break down, followed by a hands-on mission where you build this exact toolkit against your own capstone agent.
Who This Course Is For
This course assumes you can already build an agent: you are comfortable with tool use, prompting, and the basic mechanics of calling an LLM from code, and you have (or are building) a capstone agent of your own. It does not assume any prior background in evaluation, statistics, or testing. Terms like grader, rubric, groundedness, and regression suite are all introduced from first principles before they are used.
How the Course Is Structured
The course runs in five sections. Foundations of Evaluation covers why evals exist and how to choose a grader. LLM as a Judge covers building and calibrating a model-based grader. Evaluating RAG and Agents covers grading retrieval pipelines, tool-use trajectories, and the statistics of non-deterministic agent behavior. Evals in Production covers regression testing, CI/CD integration, live monitoring, and the common ways evaluation systems fail. Each section opens with a free, verified vendor course as an on-ramp and continues with original lessons that go past where that course stops. The final section closes with a one-day mission applying everything in the course to your own capstone agent.
Time Commitment and Completion
Plan for roughly a week of part-time study, matching its place as Week 6 of the program. Each unit tracks completion automatically: HTML lessons complete on view, and quizzes complete on submission, so your progress bar reflects real progress through the material.